


Signals and stimuli for auditory research, built for Jupyter.
sonore is a small Python library for making, manipulating, and analyzing sounds
the way hearing scientists think about them. Its analysis and synthesis tools
cover tones, harmonic complexes, shaped and correlated noises, ERB-spaced
subbands, invertible spectrograms, a phase vocoder, interaural cues, HRIR
spatialization of moving sources, synthetic room reverberation, and sound
texture synthesis. Levels are written as levels (snd + 6*dB), times as
seconds (snd[0.1:0.5]), and any sound at the end of a notebook cell plays.
It brings the sounds and representations of hearing research together in one coherent system, held to the following standard: every frame inverts exactly, the mathematics in its design documents is checked by standalone scripts and the code by its tests, and every example in the gallery can be heard beside the code that made it. It is built to learn from and to build on.
The name comes from Pierre Schaeffer's objet sonore, the "sound object": a
sound taken as a thing in its own right and studied for how it is heard rather
than for what produced it. The Sound object at the center of this library is
meant in the same spirit.
The logo is drawn from the spectrogram of
sonore saying its own name
with a formant synthesizer.
▶ Listen to the gallery: every sound in this README and more, each playable next to its plots, with a playhead that follows the sound.
▶ Try it in your browser: one editable cell that runs sonore on the page, through Pyodide, with nothing to install.
▶ Draw sounds with sonore-sketch: draw speech, paint a spectrogram or draw a modulation spectrum with a mouse, or erase parts of a recording's spectrogram or modulation spectrum, and hear what sonore makes of it, in your browser.

sonore is a library under active development and verification. Until version 1.0, its API may change between releases without warning, and it has not yet been fully validated for research use. Please check anything you rely on against an independent implementation.
|
Contents |
- Psychophysical stimuli. Pure tones, harmonic complexes with any phase
scheme (cosine, sine, alternating, random, Schroeder±), band-limited square,
sawtooth and pulse trains, all on a fixed F0 or following any F0 contour
(an
F0Track, or window times and values) without aliasing, chirps, band-limited and spectrally tilted noise, iterated rippled noise. Everything is reproducible from a seed. - Binaural and spatial hearing. Exact fractional ITDs, ILDs, interaurally correlated noise, Oscor and Phasewarp, windowed ITD/ILD/coherence analysis (broadband or per band), and rendering of static or moving sources through measured HRIRs (PKU-IOA, downloaded on first use, or any SOFA file), with each ear's delay sliding continuously so a source can change distance (level, travel time, Doppler) in a room.
- Synthetic speech. A Klatt-style cascade/parallel formant synthesizer (Klatt, 1980) driven by named parameter tracks (F0, formant frequencies and bandwidths, voicing, aspiration and frication levels), for vowels, consonant continua and breathy voice with every acoustic cue set exactly.
- Speech in noise. Speech-shaped noise from a long-term average spectrum, mixing at a target SNR, ideal binary and ratio masks with exact resynthesis.
- Cochlear-implant and envelope/TFS studies. A perfect-reconstruction ERB filterbank, Hilbert envelopes and fine structure, and a channel vocoder.
- Spectrotemporal modulation. Moving ripples, sums of ripples, and dynamic moving ripples, specified as patterns in time and log-frequency and rendered on tone, harmonic, noise, or low-noise carriers (or any sound's fine structure), plus a modulation spectrum in cycles/octave to verify them.
- Time and pitch manipulation. A phase vocoder (Gordon & Strawn, 1985) with phase locking: time-stretch without changing pitch, pitch-shift without changing duration, and oscillator-bank resynthesis with arbitrary frequency remapping (e.g. shifting a harmonic complex to make it inharmonic).
- Rooms. Synthetic impulse responses with frequency-dependent decay from the statistics of real rooms (Traer & McDermott, 2016), with a controllable DRR and decorrelated binaural tails, plus the paper's "unnatural" variants (time-reversed and linear decays; inverted, exaggerated and reduced frequency dependence) and a per-band RT60 measurement. A room's RT60 is one number or a curve over frequency, such as one drawn by hand.
- Sound textures. The texture model of McDermott & Simoncelli (2011):
measure a recording's envelope, modulation and correlation statistics, and
synthesize new samples that share them. A clean-room implementation with
analytic gradients; every deviation from the MATLAB toolbox is documented
(
so.texture.DIFFERENCES_FROM_TOOLBOX). - Teaching and demos. One-call overview plots (waveform, spectrum, spectrogram, modulation spectrum) next to an audio player.
sonore is not an experiment runner, does not calibrate to dB SPL, and has no models of the ear or of perception; see "Related projects" below for those.
pip install "sonore[notebook]" # extras: sofa (HRIR files), play (sounddevice), live (microphone input), dev (tests)or, for the development version:
git clone https://github.com/choyun1/sonore
cd sonore
pip install -e ".[notebook]"
Requires Python ≥ 3.11, numpy, scipy ≥ 1.12, matplotlib, and soundfile.
A first cell in a notebook:
import sonore as so
from sonore import dB

fs = 44100
tone = so.pure_tone(0.5, fs, 1000).ramp(10e-3) - 20 * dB
noise = so.gaussian_noise(0.5, fs, rng=0).ramp(10e-3) - 20 * dB
tone_in_noise = tone + (noise + 5 * dB)  # the tone at -5 dB SNR
so.overview(tone_in_noise)
tone_in_noise # a Sound at the end of a cell playsThe listening gallery has every sound beside plots of the same audio, with a playhead that follows it, and the code for each example. Three of the kinds of plot sonore draws:
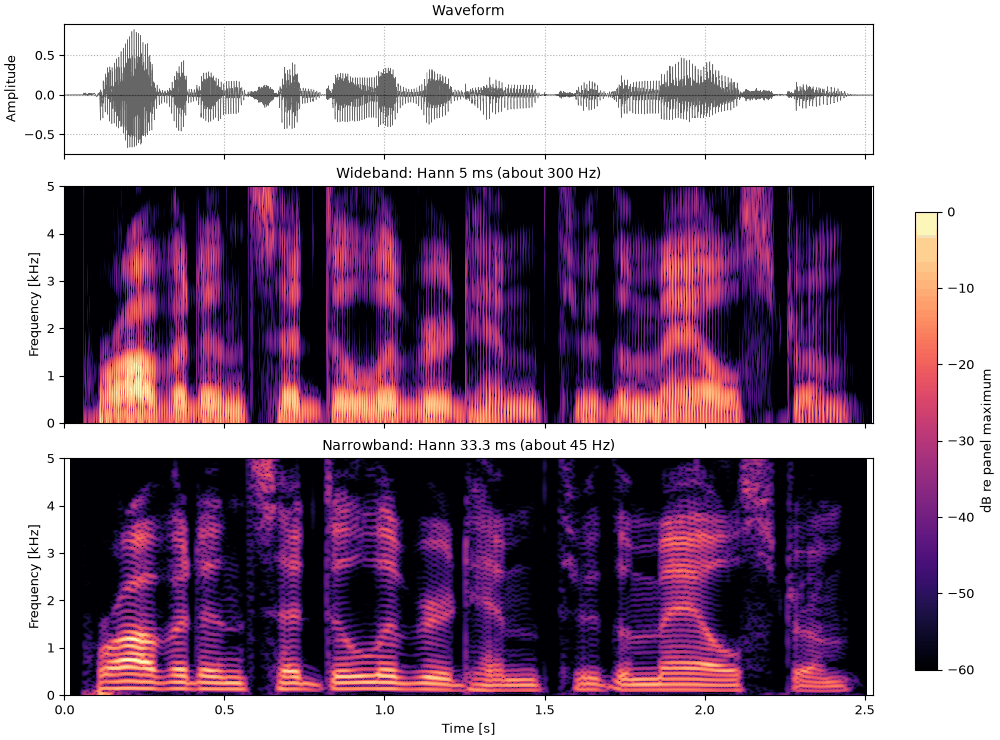
Spectrograms. One sentence, read by a male and a female talker, through a wideband (5 ms) and a narrowband (33 ms) Gabor frame: the first resolves the glottal pulses, the second the harmonics. ▶ listen
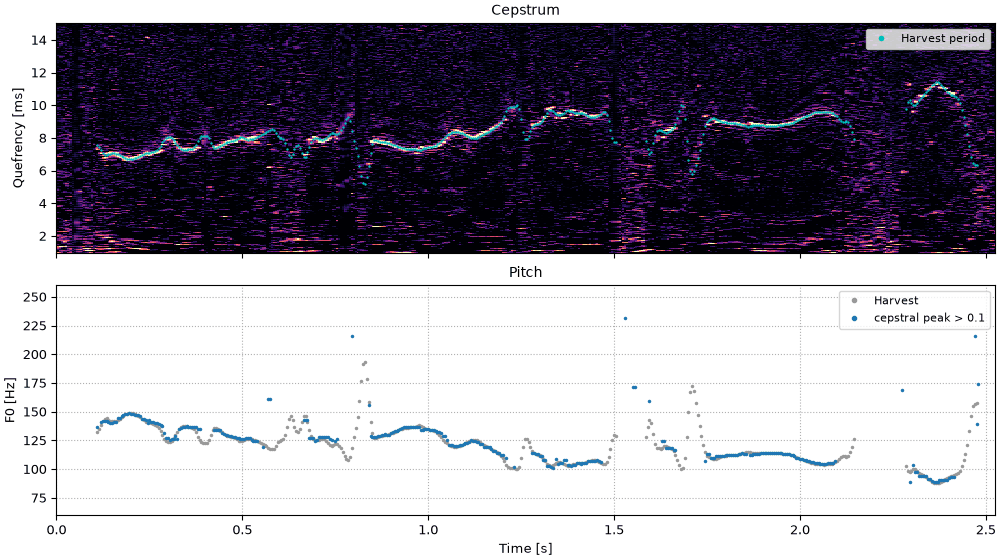
Cepstrum. The cepstrogram of the same sentence for each talker, with
so.Cepstrum's F0 beside WORLD's Harvest. ▶ listen
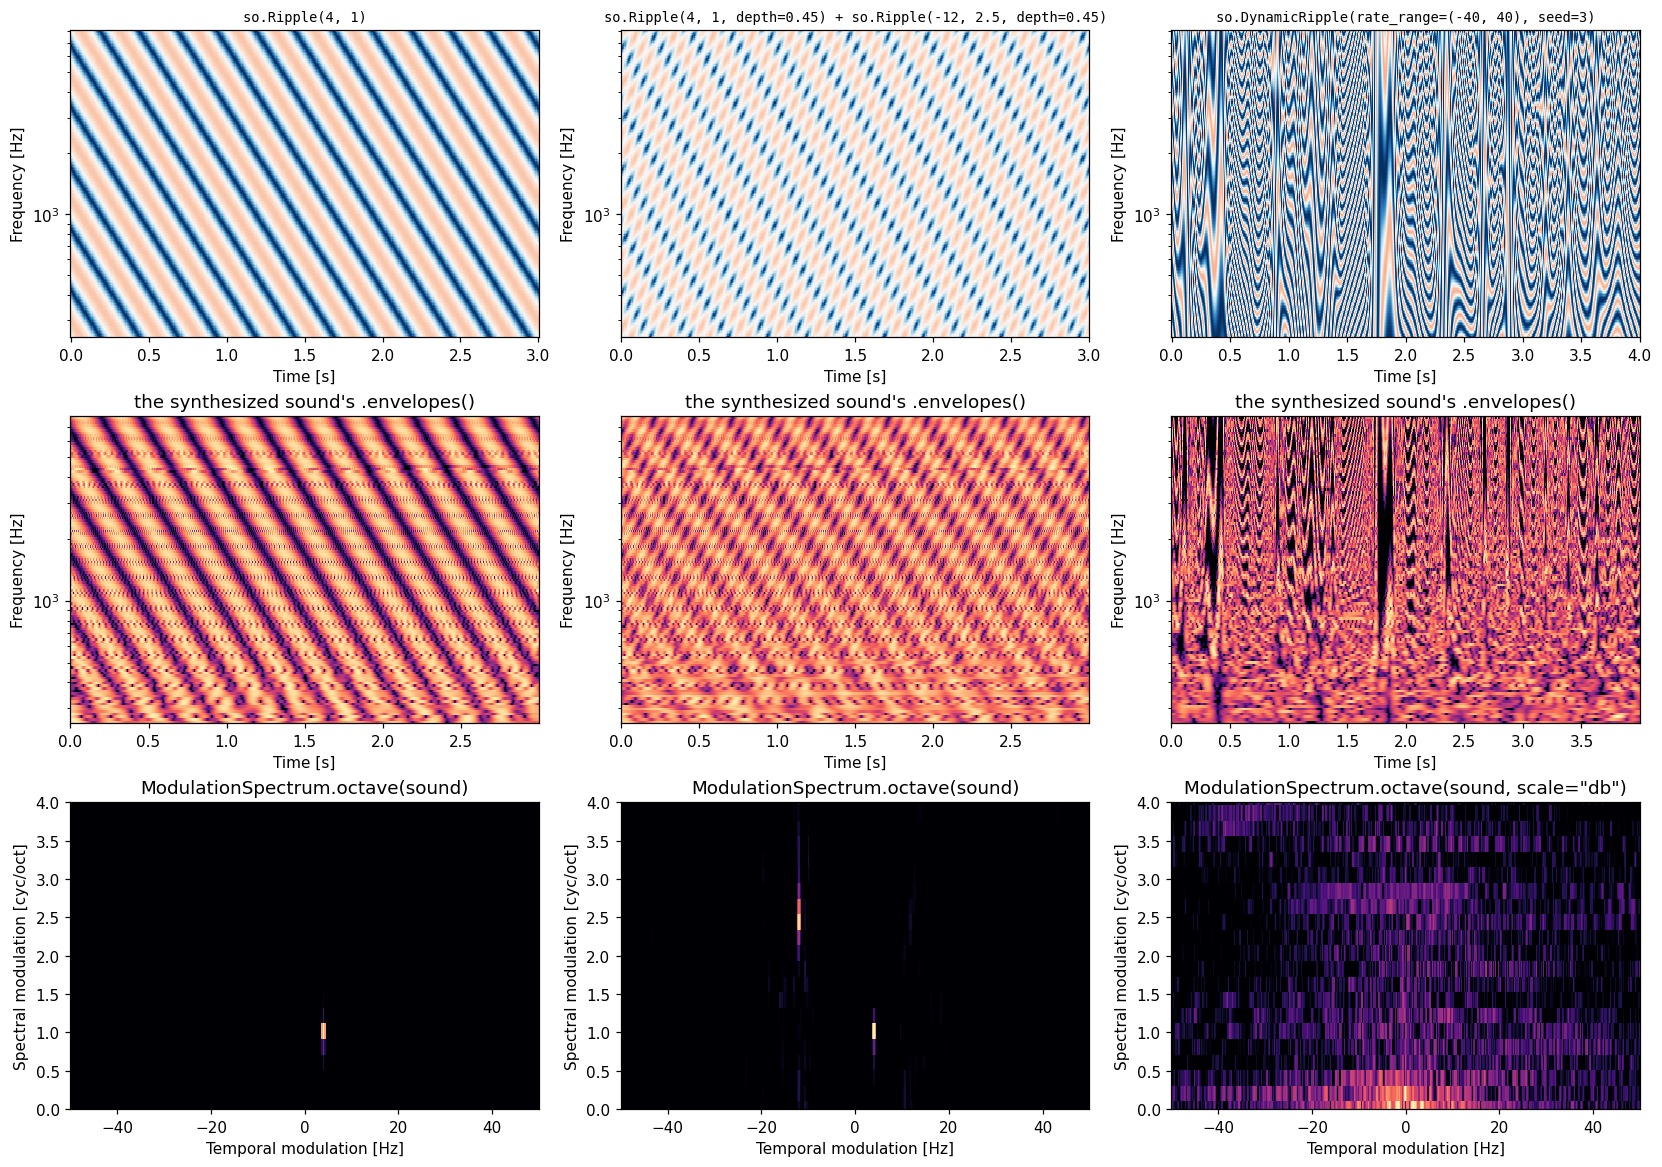
Modulation spectra. Three ripple patterns as specified (top), the
synthesized sounds' subband envelopes (middle), and their measured
so.ModulationSpectrum (bottom), which peaks at each specified rate and density.
▶ single ▶ sum of two ▶ dynamic
More in the gallery:
Synthetic sounds
- Tones and noises: speech-shaped noise, beats, tone sequences, aliasing. ▶ speech-shaped noise
- Iterated rippled noise: a pitch made from noise and a delay. ▶ sixteen iterations
- Spectrotemporal ripples: moving ripples on different carriers. ▶ dynamic ripple
Classic demonstrations (reproductions, credited to their authors)
- Streams: reproducing Bregman & Ahad: sonore's attempt to rebuild Bregman & Ahad's (1996) demonstrations of streaming from their booklet. ▶ a six-tone cycle
- Fusion: reproducing Bregman & Ahad: sonore's attempt to rebuild the demonstrations of fusion (Bregman & Ahad 1996; Houtsma, Rossing & Wagenaars 1987) and comodulation masking release (Hall, Haggard & Fernandes 1984). ▶ one harmonic mistuned
- Continuity and capture: reproducing Bregman & Ahad: sonore's attempt to rebuild the old-plus-new demonstrations (Bregman & Ahad 1996; Houtsma, Rossing & Wagenaars 1987): tones captured out of a mixture, sounds heard continuing through noise, and residuals. ▶ a tone and a noise in its gap
- Pitch of complex tones: reproducing Houtsma, Rossing & Wagenaars: sonore's attempt to rebuild the ASA pitch demonstrations (Houtsma, Rossing & Wagenaars 1987): the missing fundamental, shifted partials, melodies of virtual pitch, repetition pitch, beats and combination tones. ▶ three partials shifted off the harmonic series
- Levels and masking: reproducing Houtsma, Rossing & Wagenaars: sonore's attempt to rebuild the ASA demonstrations of level and masking (Houtsma, Rossing & Wagenaars 1987): decibel steps, filtered noise, critical bands, masking in time and frequency, and distortion. ▶ a tone staircase in noise 250 Hz wide
Seeing and changing sound
- Seeing speech: time-frequency analysis on one sentence. ▶ reassignment
- Analysis and resynthesis: perfect reconstruction, a decimated constant-Q transform with about two numbers per sample, and the ideal binary mask. ▶ binary mask
- Phase vocoder: duration, pitch and partials changed independently. ▶ up a fifth
- Hearing through a vocoder: cochlear-implant simulation. ▶ sixteen bands
- Modulation spectrogram: how each band's envelope moves, moment by moment. ▶ speech, babble, noise
- Hearing a modulation spectrum: sounds made from a measured, edited or drawn modulation spectrum. ▶ rain with a sentence's timing
Textures
- Sound textures: syntheses from statistics (McDermott & Simoncelli, 2011). ▶ stream
- Events and pops: one event copied into a texture, and the power law of a fire's pops. ▶ 30 events per second
- Sound quilts: recordings cut into segments and reordered (Overath et al., 2015). ▶ fire
Voices
- What is a voice: what a voice is made of, how voices differ, and the male and female talker every speech page uses. ▶ both
- The source-filter model: a voice built from a source and a filter, each measured back (pitch, formants, envelope), and put back together. ▶ ga ▶ formant copy ▶ buzz on the pitch track ▶ envelope only
- A richer source-filter model: an envelope measured to the pitch period, a source that is partly noise, and the phases. ▶ whispered
- Rebuilding and changing a voice: pitch and formants moved separately. ▶ one talker toward another
Spatial hearing (🎧 headphones)
- Binaural cues: timing and correlation between the ears, and height. ▶ over the head
- Rooms: distance, and rooms built from the statistics of real ones. ▶ time-reversed decay
- Moving talkers: talkers rendered through measured HRIRs. ▶ pass-by
- A "cocktail party": two to six talkers walking around the listener. ▶ six talkers
Music
- Timbre: attack, brightness and spectral flux, measured.
- Tuning and temperament: just and tempered intervals, and Twinkle, Twinkle in four tunings. ▶ just intonation
- Pitch class and height: a constant-Q filter bank, chroma, Shepard tones and the Risset glide. ▶ a scale that keeps rising
- The pipe organ: stops as additive synthesis (a template).
- Sounds.
Sound= immutable(n_samples, n_channels)float array +fs. Operations return new Sounds. - Arithmetic.
a + bmixes,a * bmultiplies sample-wise,2 * ascales, mono broadcasts to stereo. - Bands and envelopes. A filterbank's output (
Subbands) is a collection of Sounds, and so is its fine structure (.tfs()). Envelopes are not sounds: aTemporalEnvelopeis its own type, non-negative, often at a low sampling rate, and applied to sounds by multiplication. It holds one envelope, or one per band of the filterbank it keeps; the banded case is what the field calls a cochleagram. ASpectralEnvelopeis the other meaning of the word: power over frequency with the harmonics smoothed away, on a grid of time windows, whatever estimator made it. The Hilbert decomposition is literal:sb == sb.envelopes() * sb.tfs(). - Levels.
a + 6*dB,a - 3*dB. Adding a bare number is an error, so it can't be mistaken for a DC offset. dB is always20*log10(amplitude). - Time.
snd[0.1:0.5]slices by seconds;snd.datafor samples. - Randomness. Every stochastic function takes
rng=(a seed ornp.random.Generator). - Binaural. Positive ITD = right ear leads; positive ILD = right ear louder.
- Space. Meters, head-centered, x = right, y = front, z = up.
hcc= (distance cm, elevation °, azimuth ° clockwise from front). - Threads. The large FFTs (filterbanks, Hilbert envelopes, resampling) use every available core. Results don't depend on it; when running several jobs in parallel,
so.set_fft_workers(1)(also as awithblock) keeps them from competing. - Plots. Every plotting function takes an optional
axand returns it; global matplotlib settings are never touched.
The folders follow meaning. core holds Sound and the processing that
needs no analysis; sources makes sounds from parameters; frames are
analyses with an exact inverse, and views are one-way analyses together
with the routes back to sound they have (the channel vocoder, the phase
vocoder; a voice's views go back through sources.source_filter); spatial and texture are topics built on
those. Imports between modules never form a cycle, and core imports
nothing above it at module level. plotting is called from every object's
.plot(). docs/design/layout.md has the diagram.
Most names are also at the top level as so.name; the texture ones are
under so.texture and sonore.texture.synth.
| Module | Contents |
|---|---|
core.sound |
Sound, load |
core.units |
dB, Decibels |
core.utils |
rms, amp_to_db, power_to_db, db_to_amp, db_to_power, freq_to_erb, erb_to_freq, freq_to_mel, mel_to_freq (HTK or Slaney mel) |
core.fft |
set_fft_workers, fft_workers (threads for the large FFTs; default every available core; results identical for any setting) |
core.stream |
stream, blocks, Streamable, SlidingWindowStream (views computed one block of sound at a time, equal to the analysis of the whole sound: GaborFrame, Cepstrum, MFCC, the time-domain gammatone Filterbank, EnvelopePooling, ModulationSpectrogramStream, F0TrackStream) |
core.live |
live_blocks (blocks from a microphone or sound card for any stream; the live extra), DroppedSamplesError |
core.processing |
pad, truncate, concat, splice (segments of a sound in a new order, joined with cross-fades aligned by cross-correlation), mix, normalize, match_fs, match_channels, relative_db, bandpass, butter_filter, amplitude_modulate, resonator and antiresonator (Klatt's formant and antiformant; frequency and bandwidth may glide, with no clicks) |
sources.waveforms |
silence, pure_tone, harmonic_complex, schroeder_complex, square_wave, sawtooth_wave, pulse_train, linear_chirp, exponential_chirp, gaussian_noise, correlated_noise, iterated_ripple_noise, glottal_source (Liljencrants-Fant glottal pulses on a fixed F0 or a contour, shape set by Fant's Rd, which may change over time; no aliasing), lf_harmonics (the pulse's Fourier coefficients in closed form), lf_pulse (one period, to draw) |
sources.klatt |
klatt_synthesize (a Klatt-style cascade/parallel formant synthesizer: harmonic voicing with Klatt's glottal spectrum or LF pulses (SS, RD), aspiration and frication noise modulated at F0, nasal pole and zero, formants 1-5 in cascade and 1-6 in parallel, radiation; every parameter a number or a (times, values) track), klatt_continuum (evenly spaced parameter sets between two endpoints), KLATT_DEFAULTS |
sources.source_filter |
source_filter_synthesize (a voice from an F0 track, a spectral envelope and an aperiodicity: harmonics carrying the periodic part of the envelope plus white noise shaped to the rest; reads any F0 track and any envelope; checked in tools/check_voice_recipe_claims.py) |
sources.ripples |
Ripple, RippleSum, DynamicRipple, ripple_sound; patterns can also be any function f(t, x) of time and octaves, and pattern.render(filterbank, dur, fs) gives their TemporalEnvelope on that filterbank |
sources.gaussian_spectrogram |
gaussian_spectrogram (a random spectrogram whose levels correlate exponentially in time and frequency, after McDermott, Wrobleski & Oxenham, 2011; returns a TemporalEnvelope, heard through to_sound) |
sources.events |
event_train (copies of one event at random times, levels and pitches, each drawn from a distribution, with a rate that can change over time; from single events to a texture) |
frames.frame |
Frame (invertible analyses: analyze, synthesize as least squares, frame_bounds, energy, adjoint) |
frames.filterbank |
Filterbank (one class for every undecimated bank: a frequency scale, centers on it and a filter shape; canonical dual, tightness measured), cosine_filterbank (perfect-reconstruction cosine banks on the ERB, octave, mel or linear scale, any centers), gammatone_filterbank (exact gammatone responses, causal or zero-phase; envelope_peak_delay gives each filter's latency), morlet_filterbank (Morlet wavelets); all add edge filters by default so synthesis is exact on the whole band, and edges=False gives the bare bank for cochleagrams. subbands, Subbands (a collection of Sounds: .envelopes(), .tfs(), .to_sound()). DecimatedFilterbank (any bank with each band kept at its own rate, exact; on the semitone cosine bank, a decimated constant-Q transform), DecimatedSubbands (its complex coefficients, one sequence per band, with .times, .db, .plot(), .to_sound()) |
frames.gabor |
GaborFrame (the STFT as a frame; any window, zero-padded FFTs), TVGaborFrame (a Gabor frame whose window changes over time, from an explicit schedule, from_function, or pitch_adaptive from an F0 track; exact inverse; coefficients are a TVSTFT), STFT (a GaborFrame analysis: exact inverse, fast Griffin-Lim), TVSTFT (a TVGaborFrame analysis) |
views.mask |
Mask (gains for the coefficients of an STFT, TVSTFT or Subbands; multiply and go back with .to_sound()), ideal_binary_mask, ideal_ratio_mask |
views.view |
View (the base of every view: a discards sentence saying what it drops, and a synthesize and a to_sound that raise NotInvertibleError with that reason and the route back to sound, if any; views with a canonical route back override to_sound) |
views.spectra |
Spectrum (a power spectral density in dB re 1 per Hz; .to_sound with a noise, a sound's phase or the minimum phase as carrier), long_term_spectrum, tandem_power (TANDEM-STRAIGHT-style pitch-adaptive power, after Kawahara et al., 2011; magnitude only, a TFPower), reassigned_spectrogram (Kodera et al., 1978; Auger & Flandrin, 1995: spectrogram cells moved to their reassigned time and frequency, binned for display; not invertible) |
views.temporal_envelope |
TemporalEnvelope (one envelope, or one per band of a filterbank it keeps, i.e. a cochleagram; env * snd modulates, band by band through the filterbank when it has one; .plot(), .modulation_spectrum(), env * subbands, .to_sound(carrier)); channel_vocode (the channel vocoder of cochlear-implant simulations, after Shannon et al., 1995: band envelopes, lowpassed at any cutoff, on a carrier of noise, tones at the band centers, or any sound) |
views.modulation |
ConstantQModulationFilterbank, OctaveModulationFilterbank (circular, analytic output optional), HannModulationFilterbank (Hann-windowed complex kernels of a whole number of cycles, defined in time: constant Q or one fixed window, centered or causal), ModulationSpectrum (linear-frequency from an STFT, or .octave() in cycles/octave; one made from envelopes can be edited with .with_gain() and heard with .to_sound(carrier=...), the carrier supplying the modulation phase and fine structure; .from_blobs() draws a target from ModulationBlobs at a chosen rms depth, or in dB at a chosen spread, which can go deeper) |
views.modspectrogram |
ModulationSpectrogram (a modulation spectrum per time window: power, local mean and depth for every acoustic band and modulation rate, from any filterbank's TemporalEnvelope, with a valid mask; .plot() as rate against time, one band, or band against time at one rate; .at(t), .slices(t), .animate(); not invertible) |
views.cepstrum |
Cepstrum (the real cepstrum of an STFT or TVSTFT: rectangular liftering with a fixed or per-time-window cutoff, the cepstral envelope, resynthesis with the original phase, exact when unliftered, or the minimum phase, and classic cepstral F0 after Noll, 1967) |
views.mfcc |
MFCC (mel-frequency cepstral coefficients of a Sound, with the usual speech settings, or of any STFT or TVSTFT: HTK or Slaney mel, height- or area-normalized triangles straight in mel or in Hz, the mel spectrogram, deltas, the smoothed envelope the coefficients keep, .plot(); reproduces Kaldi's and librosa's numbers to rounding error; not invertible) |
views.lpc |
LPC (linear prediction of each time window of a Sound or an STFT, by the autocorrelation method and levinson: the all-pole envelope, as a SpectralEnvelope too, and every resonance from the roots; .plot(); not invertible), formant_track → FormantTrack (F1 to F3 every 5 ms: Praat's recipe for candidates, within a few hertz of Praat's own, and a Viterbi tracker; .track(n) gives the (times, values) that klatt_synthesize takes; .plot()) |
views.f0 |
f0_track → F0Track (F0 every 5 ms with a voiced/unvoiced decision: candidates from YIN's difference function, refinement by the instantaneous frequency of the harmonics up to 1.5 kHz, a periodicity score, a Viterbi pass; .plot(); checked against laryngograph F0), scale_f0 (a pitch change on any F0 contour, with a range factor) |
views.timbre |
log_attack_time and attack_segment (the attack by Peeters et al.'s weakest-effort method), spectral_centroid (magnitude spectrum by default, as the paper) and spectral_flux → DescriptorTrack (one value per 5.8 ms, with .median and .iqr); timbre descriptors written from Peeters et al. (2011), checked in tools/check_timbre_claims.py |
views.chroma |
chroma → Chroma (the power in each of the 12 pitch classes per 0.05 s time window, from a cosine filterbank with one band per semitone, A1 to A8, the octaves added together); Chroma.to_sound(fs, octaves=...) plays each pitch class as a Shepard tone, with octaves saying how the power spreads over octaves; checked in tools/check_chroma_claims.py |
views.spectral_envelope |
pitch_adaptive_envelope → SpectralEnvelope (CheapTrick, written from Morise's 2015 paper; within 0.01 dB of WORLD's at the paper's q1), warp_frequency (formants moved along frequency on any envelope or aperiodicity, by a ratio, a ratio over time or any frequency map), SpectralEnvelope (any envelope as power on a grid of time windows and frequencies, labelled by the method that made it: CheapTrick, or Cepstrum.envelope_view(), MFCC.envelope_view() and LPC.envelope_view()), TimeFrequencyGrid (the Protocol for anything on such a grid that the synthesizers read) |
views.aperiodicity |
band_aperiodicity → Aperiodicity (D4C, written from Morise's 2016 paper, with its measured 8 dB bias corrected), harmonic_aperiodicity (the share of noise, by fitting the harmonics) |
views.phasevocoder |
time_stretch, pitch_shift (identity phase locking), pv_analyze → PVAnalysis (instantaneous frequency; oscillator-bank to_sound with time_scale and freq_map) |
views.quilting |
quilt (the sound quilts of Overath et al., 2015: segments of a sound in a new order, each chosen so that its join changes the cochleagram as much as the sound itself did there; written from the paper's methods) |
views.envelope_peaks |
envelope_peaks → EnvelopePeaks (how big a sound's pops are: the largest envelope value in each 5 ms bin above 300 Hz and 2 kHz, and the power-law exponent of their upper tail by the Hill estimator, with its uncertainty; .plot()) |
spatial.binaural |
apply_itd_ild, simple_bir, interaural_cues, oscor, phasewarp |
spatial.spatialization |
HRIRSet (PKU-IOA, SOFA; onset-aligned interpolation), spatialize, move_sound (paths as functions of time, continuous ear delays, room tail), hcc_trajectory and other trajectories, coordinate conversions, distance_gain_db |
spatial.hrir_data |
load_hrirs: public HRIR databases (PKU-IOA) downloaded on first use, checksum-verified and cached |
spatial.reverb |
synth_ir (natural rooms, or the paper's atypical decay_shape / rt60_profile / drr_profile variants; rt60 is a number or a curve (freqs, rt60s)), band_rt60s, measure_rt60 |
texture.stats |
TextureModel, TextureStats (.measure, .snr, .replace for hybrids, .save/.load) |
texture.synth |
synthesize (full loop), impose_channel; gradients in texture.grad |
plotting |
overview and the plot_* functions behind each object's .plot(); plot_tf_db draws any time-frequency level on non-uniform time windows; modulation spectrograms draw invalid cells gray and animate with their sound; cochleagrams take align="peak" (draw causal gammatone bands without their latency) and fscale="linear" (to match spectrograms) |
Where to go for what sonore leaves out:
-
slab: calibrated levels in dB SPL, playback, trial sequences and adaptive staircases. Its sound making overlaps with sonore's, and the two share the same sample layout (samples × channels), so a sound passes between them in one line:
s = slab.Sound(snd.data, samplerate=snd.fs)  # sonore to slab; then set s.level in dB SPL
snd = so.Sound(s.data, s.samplerate)  # slab to sonore
slab reads samples as pascals, so a sonore sound at RMS 1 shows as 94 dB SPL until you set its level.
-
PsychoPy: running experiments.
-
Auditory Modeling Toolbox (MATLAB/Octave) and torch_amt (PyTorch): models of the auditory system that predict what a listener hears.
-
brian2hears: auditory periphery and spiking models.
-
MoSQITo: loudness, sharpness, roughness and other sound quality metrics.
-
Parselmouth (Praat in Python) and pyworld (WORLD): speech analysis and synthesis.
-
librosa: music and audio analysis.
-
pyroomacoustics: geometric room simulation.
-
sonore-sketch (source): five tabs, each one of sonore's routes back to sound with a surface to draw on. Draw speech (formant tracks for the Klatt synthesizer), Paint spectrogram, Erase spectrogram (of a recording), Draw modulation (blobs on a modulation spectrum) and Erase modulation (of a recording). It runs sonore in the browser, with nothing to install.
Only work still to do is listed here. Finished items are in docs/roadmap-done.md, and changes by release in CHANGELOG.md.
- Hand-written intro pages for the API reference, one per folder: the last step of the code audit (issue #48).
- The rest of KLSYN88's voice-quality controls (Klatt & Klatt, 1990) for the formant synthesizer: open quotient, spectral tilt, flutter, double pulsing, and its KLGLOTT88 source.
- Peak-based sinusoidal modeling (McAulay & Quatieri, 1986) alongside the channel oscillator bank.
- Routes back to sound from a sharpened time-frequency picture: a synchrosqueezed STFT (the coefficients moved in frequency only, so it stays exactly invertible) and partials tracked on the reassigned spectrogram, played by an oscillator bank (as in Fitz & Haken's Loris).
- On-demand download of other public HRIR databases.
- Live input in the browser: a page that runs the streaming views on the
microphone. The Python side,
so.live_blocks(thesonore[live]extra), is in but has only been tested with a stand-in for the sound card. - Quilts longer than their source, which would reuse segments. The paper's rule picks the best match every time, so a reused segment would start a loop that repeats; it would need a random pick among the best few and a minimum gap before a segment returns. That would be sonore's own variant, to be checked by ear for repeats.
The works sonore implements, follows or cites are listed in docs/references.md, each with a link to the work, tags linking to the code that implements it, and the gallery pages that use it. The same page lists the reference implementations sonore was checked against or consulted.
pip install -e ".[dev]"
pytest                             # ~40 s; one test file per module
ruff check . && ruff format .
python docs/gallery/build.py       # regenerate the listening gallery (a few minutes)
How to report a problem or propose a change, and what support to expect: CONTRIBUTING.md.
sonore began as sigtools, the code I (Adrian Cho) wrote in graduate school to make psychoacoustic stimuli (migrating from sigtools). The 0.2 redesign and everything since were developed together with Claude, Anthropic's AI assistant, in chat sessions during 2026.
What Claude did. Wrote most of the code, tests, documentation, and gallery since 0.2, delivered as patches; drafted design documents; ran numerical checks and profiling; and looked up and checked citations.
What I did. Decided what sonore is for and what goes in it, including its API conventions, the texture work and its milestones, and the roadmap and architecture. I chose and documented the texture recordings and set the working rules: implement from the papers, verify every claim numerically, document every deviation and data choice, and write a design document before large features. I reviewed and applied each patch. The design principles that came out of this are summarized in docs/design/philosophy.md.
How it is verified. I have not read every line by hand. A code audit went
through every module of src/sonore, one sitting per module
(issue #48): Claude wrote a
reading guide for each (every claim the code makes and the test behind it, the
lines no test runs, the results of deliberately breaking the code), I read the
guide and parts of the code, and each sitting fixed the bugs it found and
closed the gaps in the tests. Besides the audit, I rely on the following:
- The test suite, with one file per module.
- Finite-difference and dense-matrix checks of the mathematics.
- Cross-checks against independent implementations (see "Reference implementations").
- Written records of every decision (
DIFFERENCES_FROM_TOOLBOX,docs/textures/SOURCES.md,docs/design/). - The listening gallery, since these are sounds and should be heard.
I am responsible for sonore's correctness. If something is wrong, please open an issue.
MIT; see LICENSE. pitch_adaptive_envelope
(CheapTrick) and band_aperiodicity (D4C) are written from Morise's papers, not ported from WORLD's
code, and sonore's F0 tracker is its own, not WORLD's. If sonore is useful in your research, please cite
it using CITATION.cff; the
Cite this repository button in the GitHub sidebar gives the same citation in APA and BibTeX.
Every release is archived on Zenodo. The all-versions DOI

- 0.10.0:
- 0.9.0:
- 0.8.0:
- 0.7.0:
- 0.6.0:
- 0.5.0:
- 0.4.0:
- 0.3.1:


